Abstract
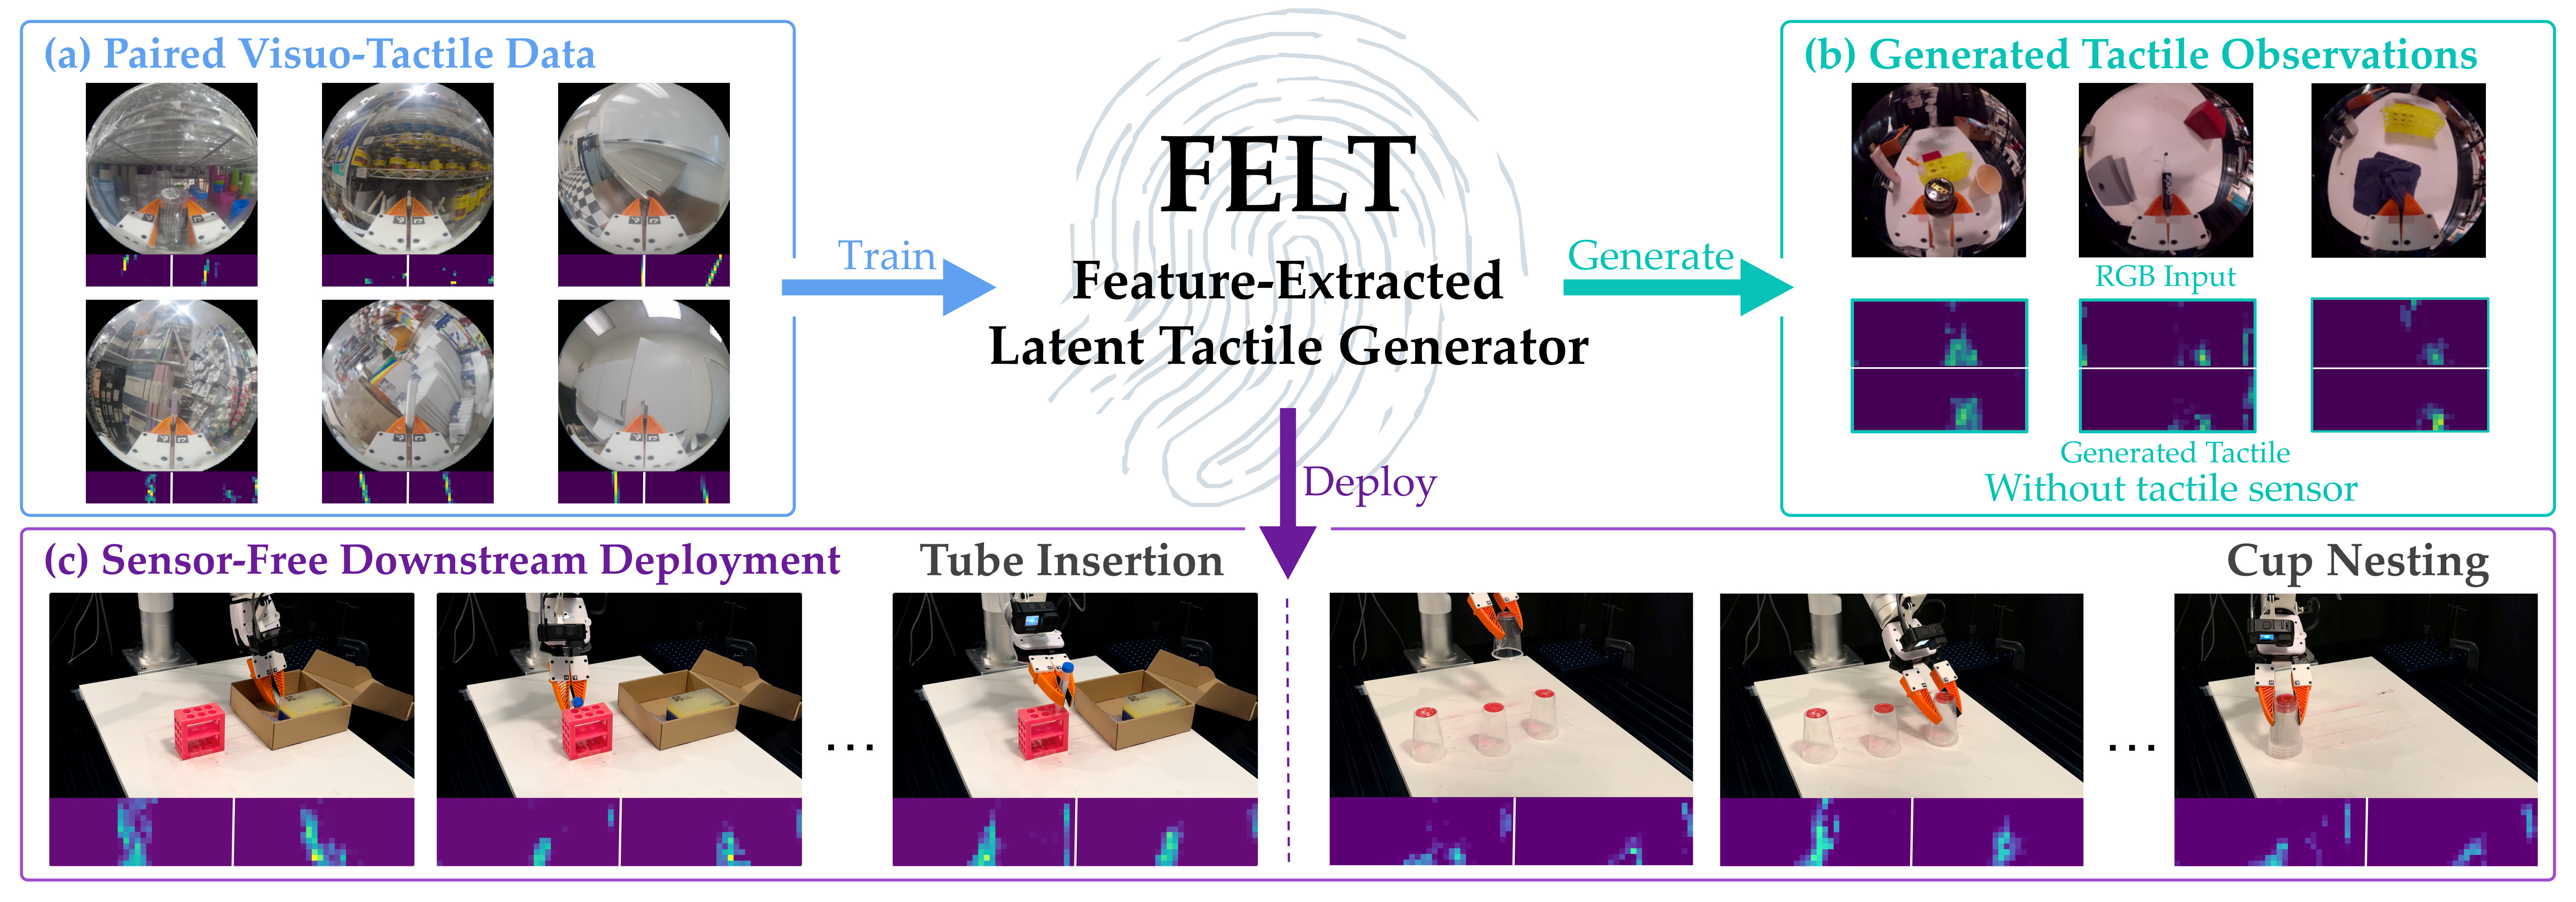
Tactile sensing can improve performance in contact-rich robot manipulation. However, learning policies that use real tactile feedback typically requires demonstrations collected with tactile-equipped hardware.
We present Feature-Extracted Latent Tactile (FELT), a framework that uses existing paired visuo-tactile data to learn contact-aware representations from RGB observations. FELT provides these representations to downstream policies through two interfaces: generated tactile images and contact-aware features. FELT combines a frozen visual encoder with separate query decoders for the left and right finger, reflecting the spatial organization of dual-finger tactile arrays. The two branches exchange information through gated connections, and a convolutional readout produces spatial contact representations for the downstream interfaces.
For downstream manipulation, the image interface decodes these spatial representations into tactile images, allowing policies trained with either real or generated tactile observations to use generated images at deployment. Alternatively, the feature interface feeds these representations directly to the policy during both training and deployment, without real tactile observations. Experiments on four contact-rich real-robot tasks show that both interfaces achieve higher success rates than vision-only policies. Directly incorporating learned contact-aware features into the policy improves success by 15-22.5 percentage points across the four tasks.
Method
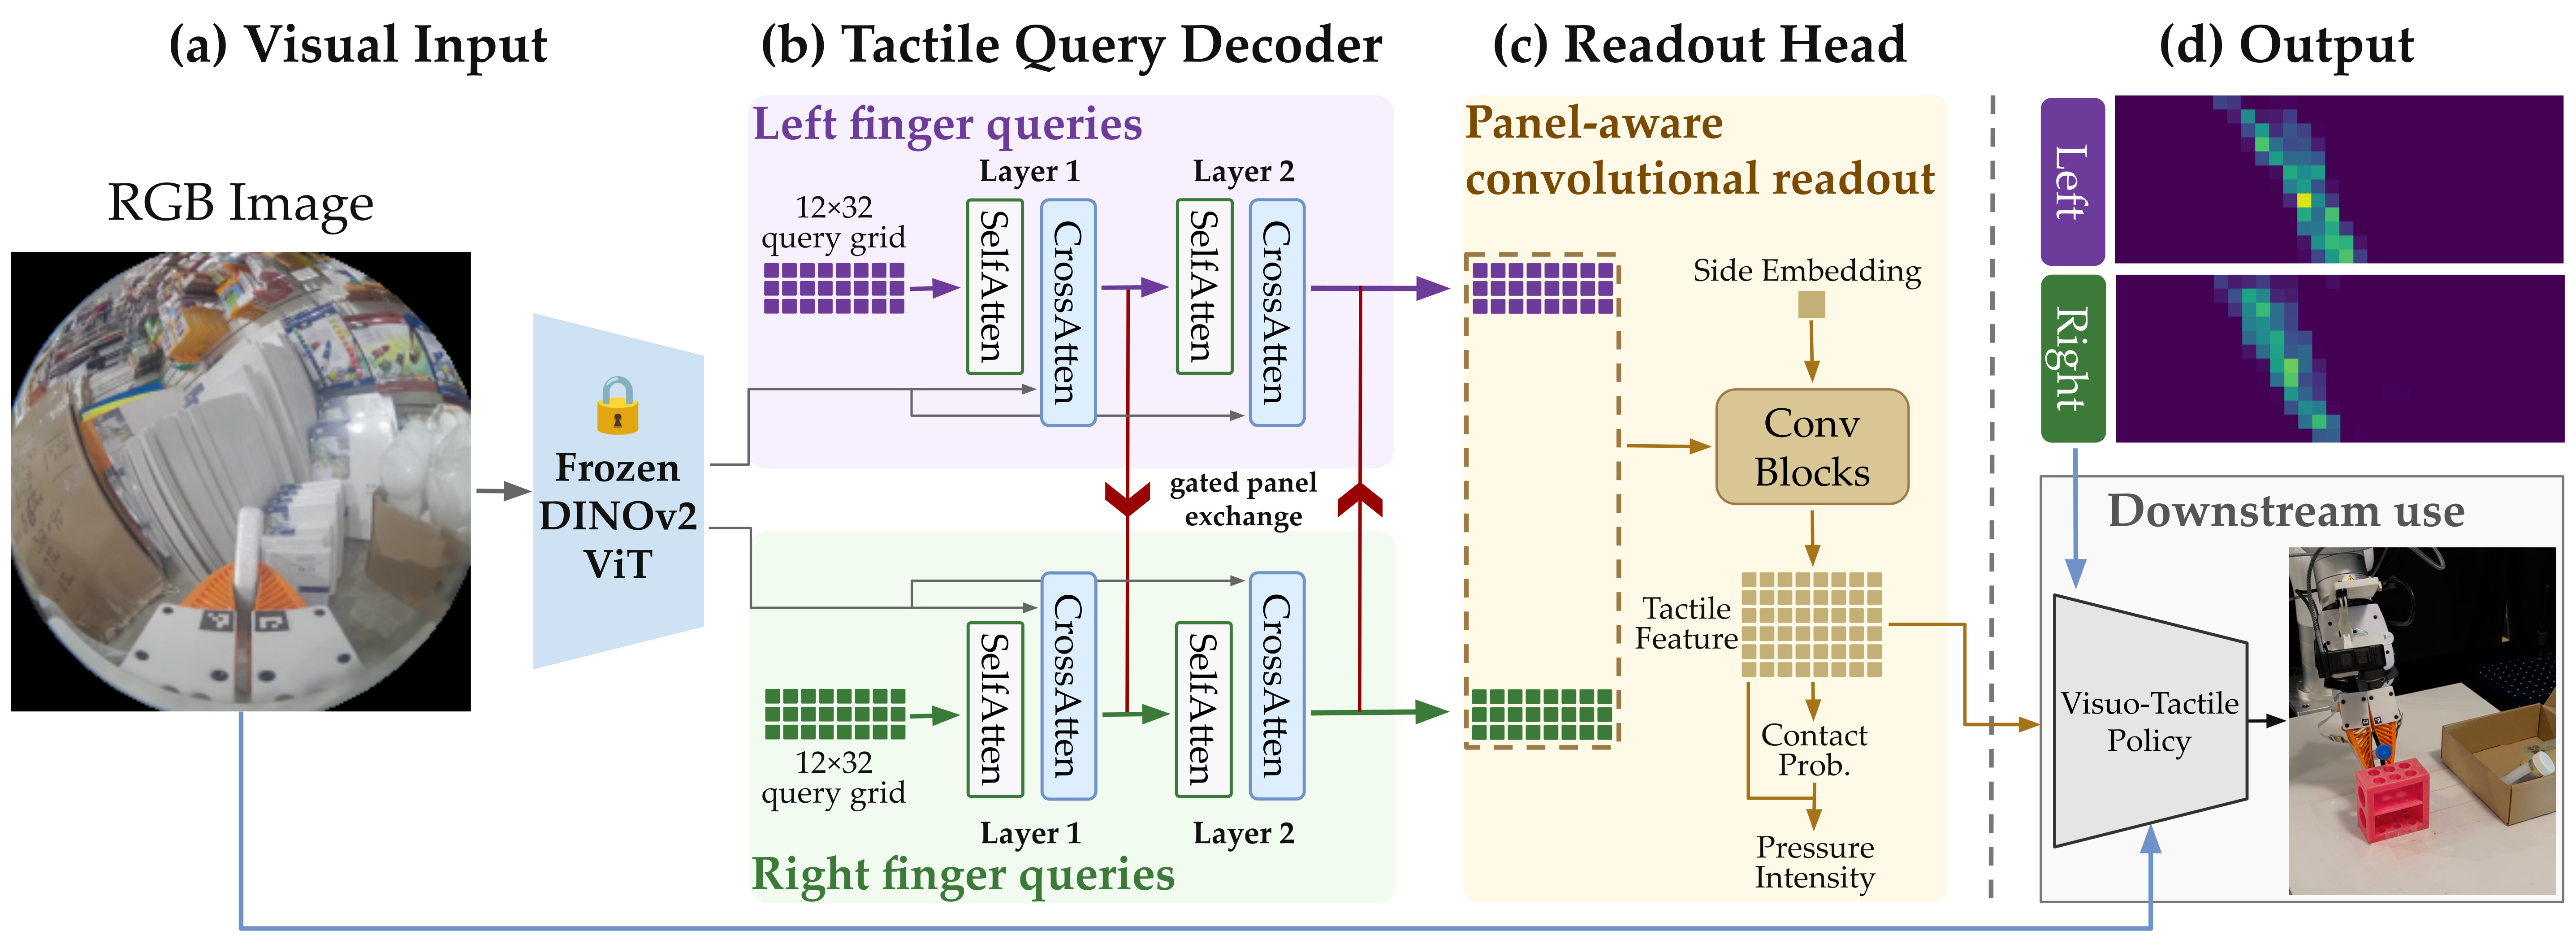
Overview of FELT's spatial, per-finger contact representation framework. (a) Given a fisheye RGB observation, FELT extracts visual features using a frozen, pretrained DINOv2 ViT. (b) Separate decoders for the left and right finger panels use learnable, position-aware queries aligned with each panel's spatial grid. Each branch attends to the visual features through cross-attention, while gated cross-panel connections enable information exchange between the two branches. (c) A panel-aware convolutional readout transforms the decoded queries into spatial contact features, with learned side embeddings to distinguish the left and right panels. Prediction heads map these features to per-cell contact probabilities and conditional contact intensities. (d) FELT provides two interfaces for downstream manipulation: generated tactile images and contact-aware features.
Tactile Prediction Results
We compare the predicted tactile images from FELT with ground-truth in our xArm test dataset.
Downstream Sensor-free Deployment
Policies trained with RGB and real tactile data, but deployed with FELT-generated tactile images in place of the physical sensor reading.